This signal is still in the schedule queue.
Open Source Just Beat Google's TurboQuant 🚀
Running LLMs locally eats your VRAM alive because of massive KV caches. Enter Rotorquant. It uses simplified block-diagonal rotations to compress KV caches by over ten times. No complex butterfly networks. It drops right into llama dot cpp. Compared to TurboQuant, it’s five times faster at prefill, uses forty-four times fewer parameters, and actually delivers better perplexity. This means you can run huge models locally with way less memory and zero quality loss.
More signals
01
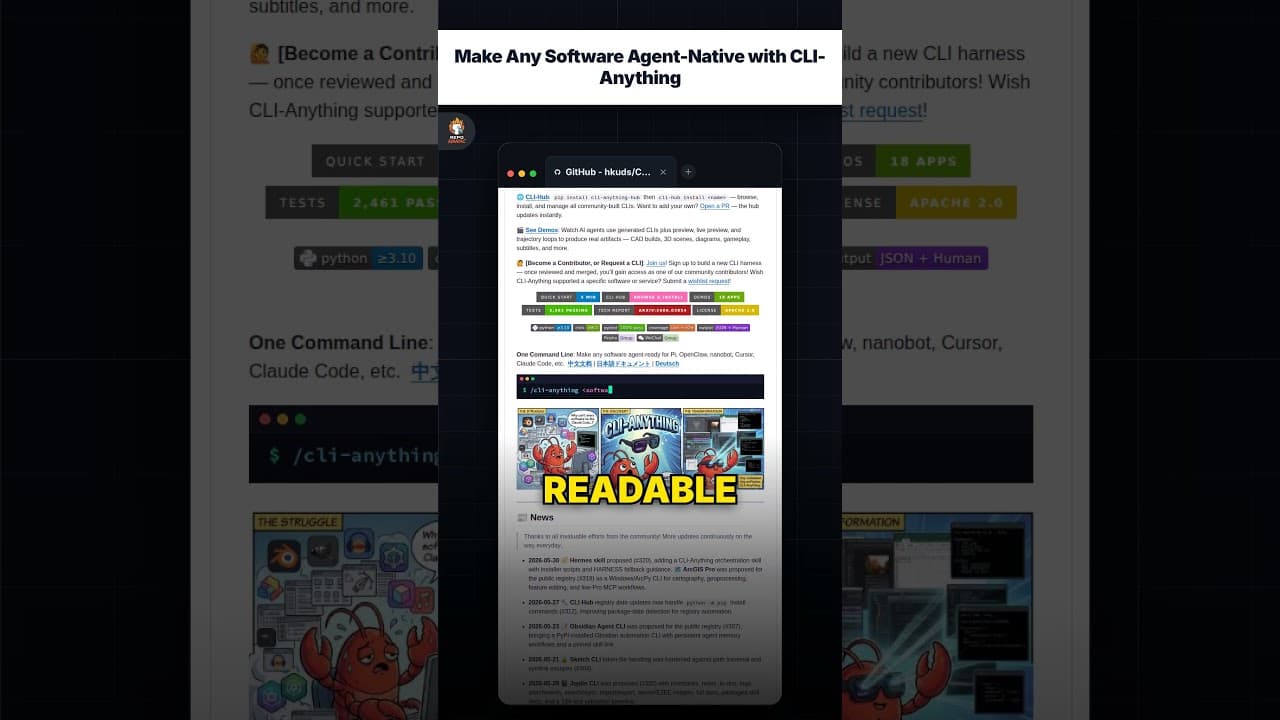
Make Any Software Agent-Native with CLI-Anything
00:39Sep 07, 2026score98
02
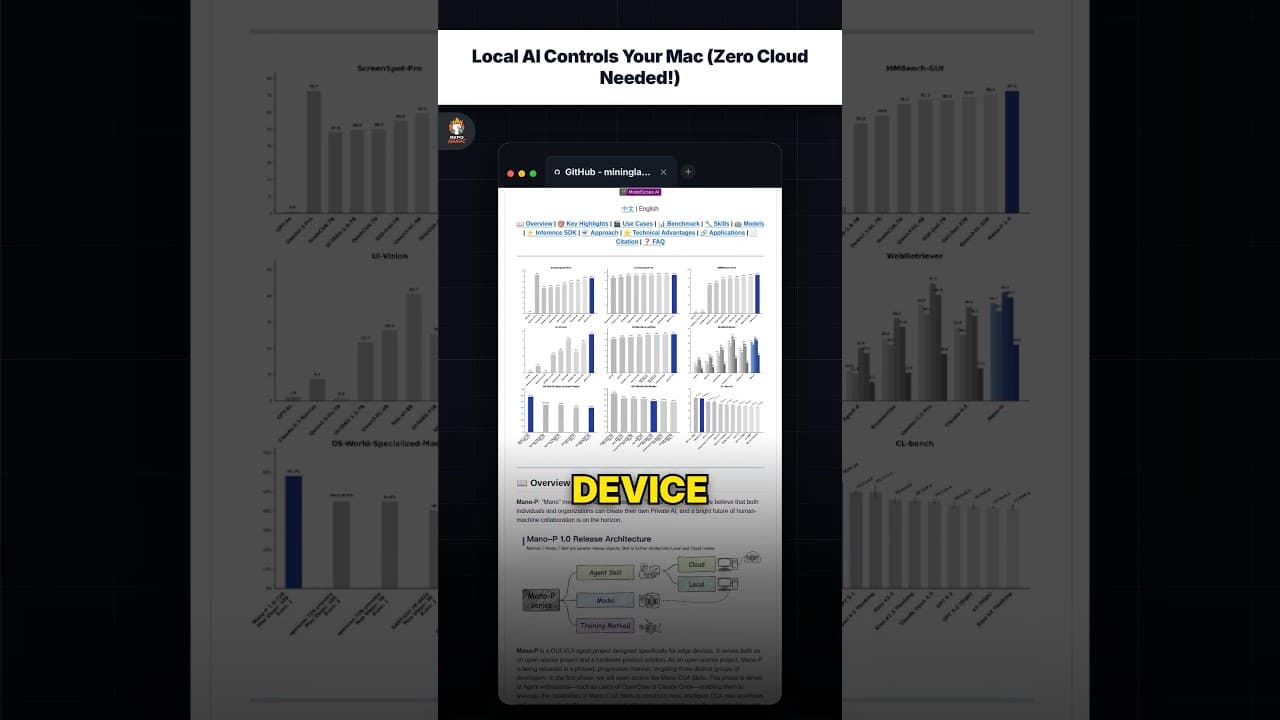
Local AI Controls Your Mac (Zero Cloud Needed!)
00:33Sep 06, 2026score95
03
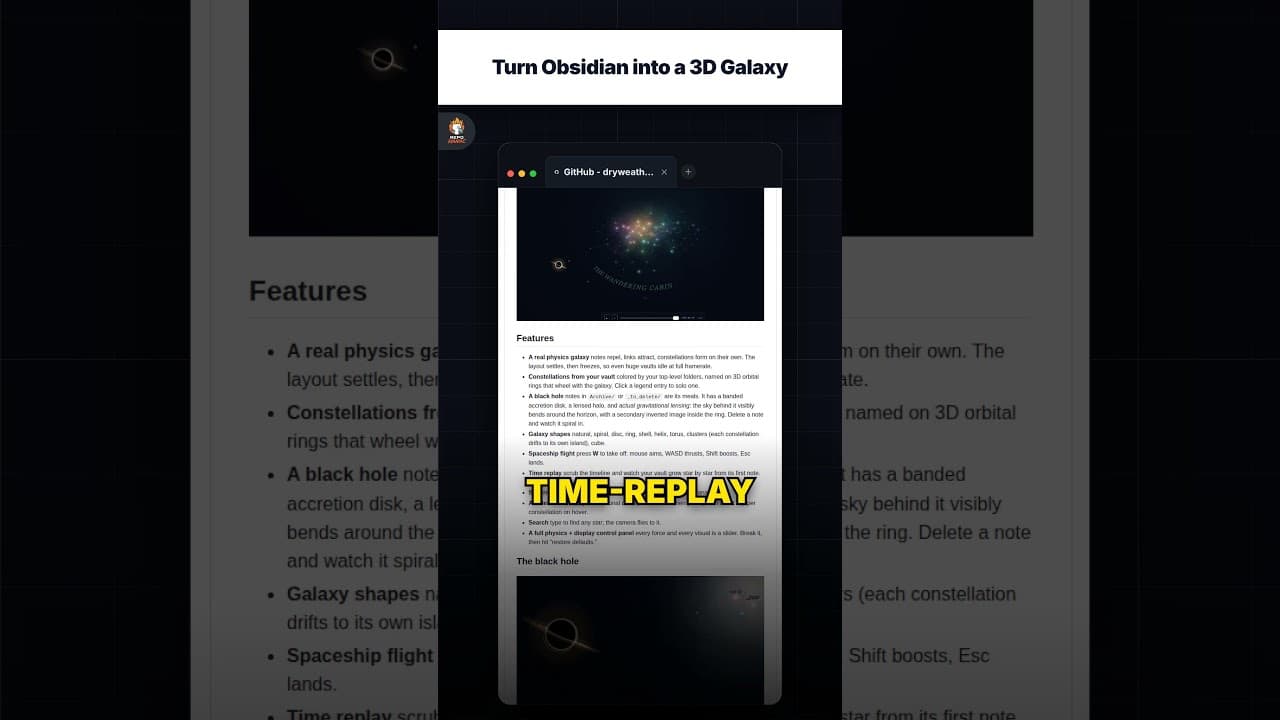
Turn Obsidian into a 3D Galaxy
00:35Sep 05, 2026score95