This signal is still in the schedule queue.
Unlocking Hopper GPUs: Maximize Attention Speed with FlashKDA
Standard linear attention struggles to max out Hopper GPUs. Enter FlashKDA by Moonshot AI. It delivers high-performance Kimi Delta Attention CUDA kernels built on CUTLASS. It auto-dispatches perfectly into the flash-linear-attention library, bypassing Triton for bare-metal speed on SM90 chips. Attention computation bottlenecks AI scaling. These drop-in PyTorch kernels maximize your hardware efficiency, saving you expensive compute time.
More signals
01
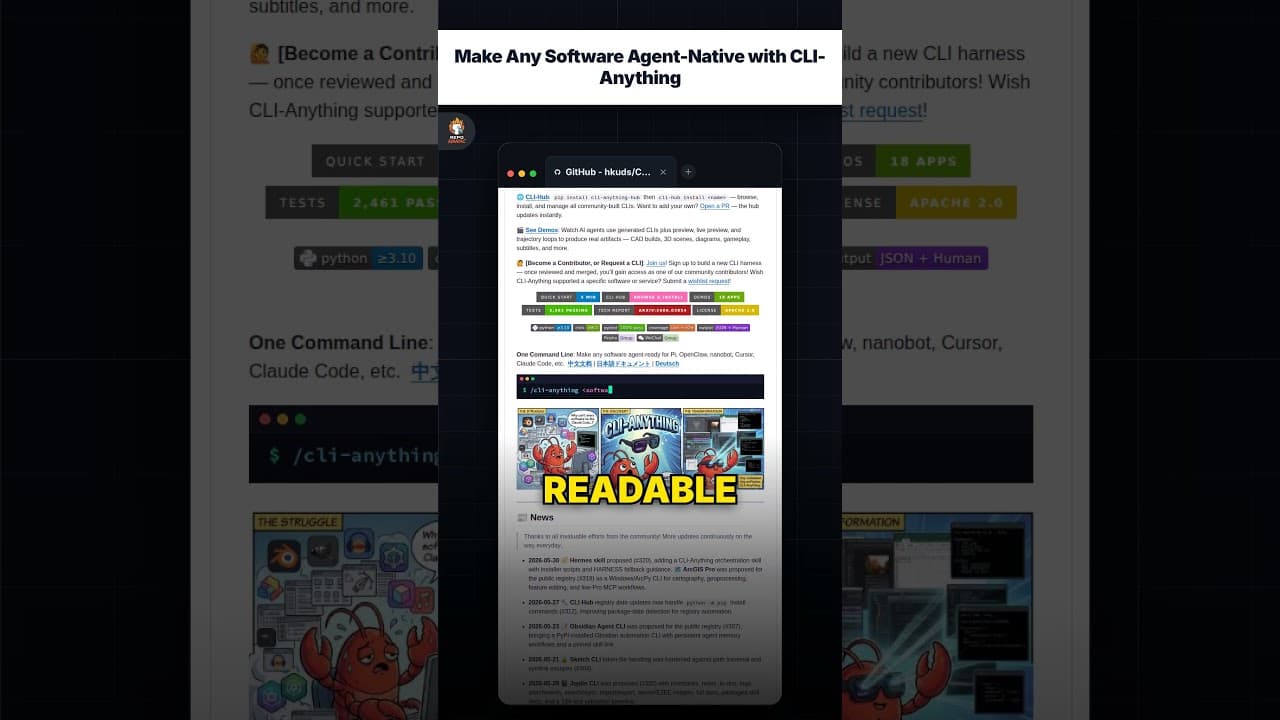
Make Any Software Agent-Native with CLI-Anything
00:39Sep 07, 2026score98
02
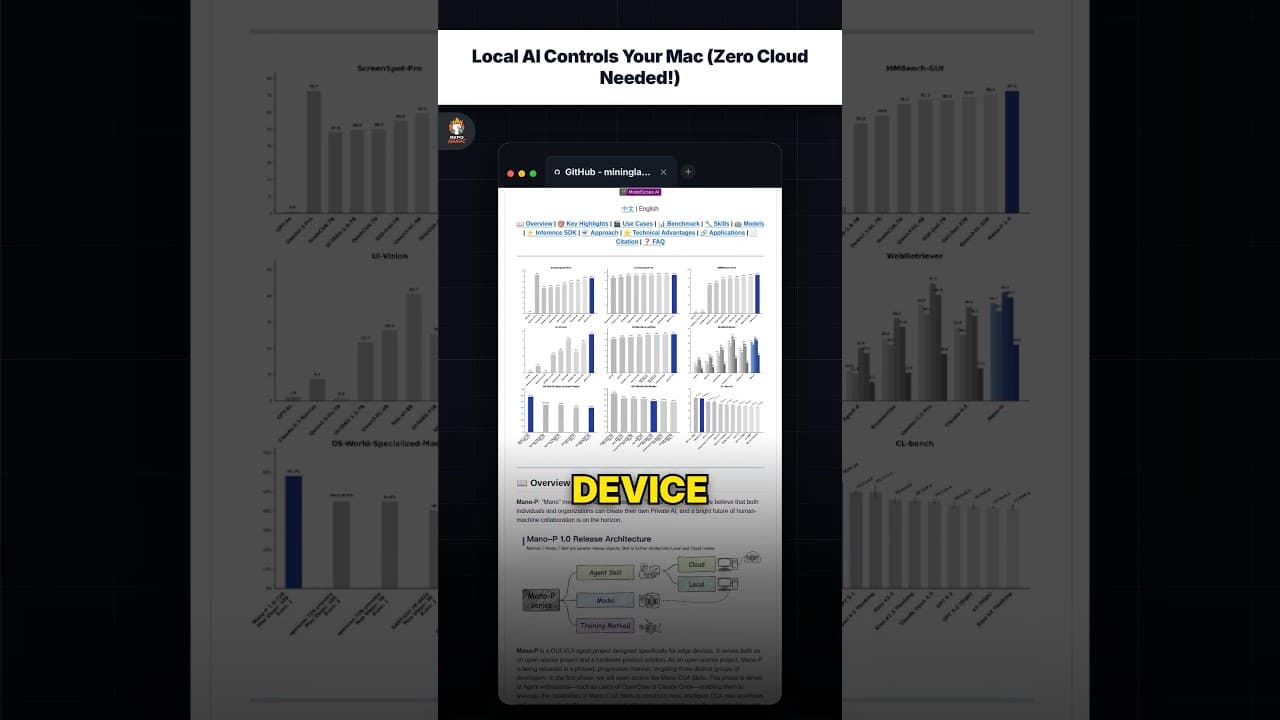
Local AI Controls Your Mac (Zero Cloud Needed!)
00:33Sep 06, 2026score95
03
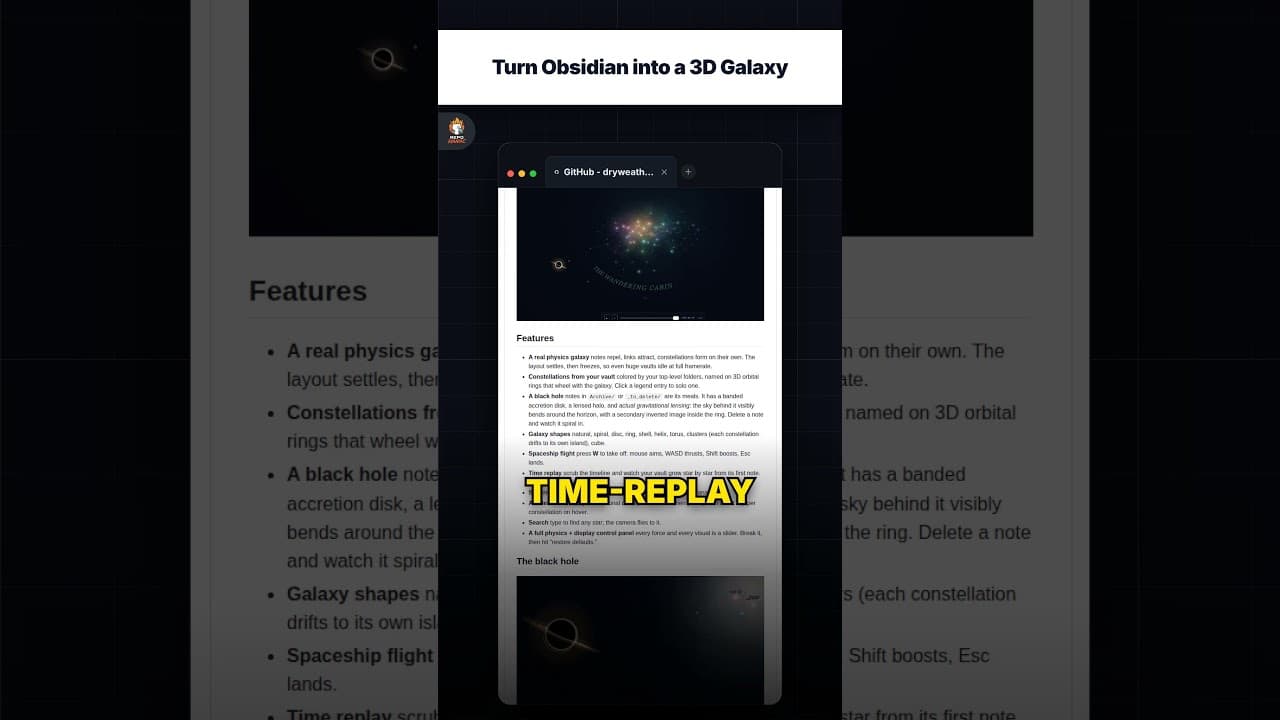
Turn Obsidian into a 3D Galaxy
00:35Sep 05, 2026score95